Automated Product Matching, Part II: Guidelines

This post continues the discussion from Automated Product Matching, Part I: Challenges.

System First, Algorithm Second

With each design iteration, I gradually came to appreciate how important it was to have an overall matching system that was well designed. The quality of the matching algorithm did not matter if its output was going to be impacted by failures in other parts of the system. The mistake of focusing on the algorithmic design first, and the system design second means that you wind up with an interesting technical talk, but you have not really solved the problem for the end users and/or the business. An example from my past experience might help give flavor for why the system view matters just as much as the algorithmic view.

In one of the earlier systems I worked on, after having successfully defined how to build a set of “canonical” products which would be used to match against all our incoming data, and having created a reasonably good matching algorithm, we were happy that we could now continually process and match all of our data each day and at scale. The problem was solved, but only in a static sense. We chose to ignore how new products would get into the canonical set. As time went on, this became more and more of a problem, until we finally had to address this omission. This was about the time when iPads first hit the market and the lack of freshness became glaringly obvious to anyone looking at iPads on our web site.

There was nothing algorithmically challenging about solving this: we knew how to create canonical products, but the code we built did not support adding new canonical products easily. Although the guts of the algorithmic logic could be re-used, the vast majority of the code that comprised the system we built around it needed to be redesigned. A little forethought here would have saved many months of additional work, not to mention all the bad user experiences that we were delivering due to our lack of matching newer products.

“A good algorithm in a bad system is indistinguishable from a bad algorithm.”

Keep it Simple

The difficulty of matching products ranges from easy to impossible. I recommend starting with an algorithm that focuses on matching the easiest things first and building a system around that. This allows you to start working on the important system issues sooner and get some form of product matching working faster. From a system design perspective, the product data needs to find its way to the matching algorithm, you will need a data model and data storage for the matches, you also need some access layer for the matches and you likely need to have some system for evaluating and managing the product matches.

The matching logic itself will be a very small percentage of the code you have to write and there are plenty of challenges in all these other areas. There are important lessons to be learned just in putting the system together, and even the simplest matching logic will lead to a greater understanding of how to build the appropriate data models you will need.

“For the human makers of things, the incompleteness and inconsistencies of our ideas become clear only during implementation.”

People cannot be Ignored

The topic name of “automated matching” implies that people will not be involved. Combine this with engineers who are conditioned to build systems that remove the rote, manual work from tasks and there is the risk of being completely blind to a few important questions.

Most fundamentally, you should ask whether you really need automated matching and whether it will be the most cost-effective solution. This is going to be determined by the scale of your problem. If your matching needs are on the order of only thousands of products, there are crowd-source solutions that make manual matching a very viable option. If your scale is on the order of millions, manual matching is not out of the question, though it may take some time and money to get through all the work. Once you get into the range of tens of millions, you likely have little choice but to use some form of automated matching.

Another option is a hybrid approach that uses algorithms to generate candidate matches and has people assigned to accept or reject the matches. This puts less pressure on the accuracy requirements of your algorithms and makes the people process more efficient, so it can be viewed as an optimization of a manual matching system. An approach that scales slightly better is to automatically match the easy products and defer the harder ones to manual matching or verification.

The other question about human involvement depends on how the quality of the matching system will be measured. Building training and/or evaluation data sets will likely require some human input and tools to support this work. Considering how feedback will be used is important because it can have an impact on the matching system and algorithm designs. Evaluation will likely need to be an ongoing process, so make sure consideration is given to the longer term human resource requirements.

“It ain’t what you don’t know that gets you into trouble. It’s what you know for sure that just ain’t so.” — Mark Twain

One Algorithm will not Rule Them All

Simply put: it is not possible for a single algorithm to do equally well matching all types of products. It is possible to use the same class of algorithm on some parts of the product category space, but you will need to parameterize the algorithm with category-specific information. Here are a couple examples to illustrate this point.

Consider the color attribute of a product. For a product like a dishwasher, color is a secondary characteristic and would be unimportant for the purpose of review content. For some types of products, say a computer monitor, the color might not even matter for price comparisons. For a $50 savings, many people are not going to care if their monitor is black or silver. On the other hand, for products like cosmetics, the color is the most essential feature of the product. If your algorithm universally treats all attributes the same while matching, regardless of the type of product it is, then it will necessarily perform poorly in some categories.

To get better accuracy you will have to invest in human domain expertise in either encoding domain-specific information, or training algorithms for each product category. If you have ever taken a hard look at camera products, there is a lot of cryptic symbology in the lens specifications and the other camera accessories. Without encoding knowledge from a domain expert, it is not going to be possible to match these types of products well. There’s no silver bullet. You can decide to allocate your time to one set of categories over another, but you should expect limited accuracy in the areas you have not invested in.

Another example lies in the contrast between consumer electronics and books. The product titles for consumer electronics are descriptive in that they contain a list of product features. With a rich enough title, there are enough features to yield relatively high confidence in matches. However, titles for books are arbitrary words and phrases chosen by the author and may give you little understanding of the contents. Similarity between book titles is not correlated with the similarity of their content.

“Do not mistake knowing something for knowing everything.”

Products are Not Strings

String-based matching algorithms may suffice depending on your targets for accuracy and coverage, but there is a hard limit on how well they will perform without imparting semantics to the strings. Not all words in product titles are created equal, so it helps to do something that is akin to part of speech tagging (e.g., The product “noun” is much more important than a product’s adjective, such as its color). Showing two different dishwashers as being the same might be a data error, but it is a characteristically different user experience than showing a dishwasher and a shoe as being the same. A string comparison algorithm might match the shoe to the dishwasher because it had the same color plus a few other strings in common, but no understanding that the mismatch of nouns “shoe” and “dishwasher” should trump anything else that might be indicating that they are similar.

You will need more than just adjectives and nouns though. There are many different types of adjectives used to describe products. There are colors, materials, dimensions, quantities, shapes, patterns, etc. and depending on the types of product, these may or may not matter in how you want to define product equivalence.

It is also true that just because two strings are different, it is not necessarily the case that they are referring to two different concepts. If you do not encode the knowledge that “loafer” and “shoe” are semantically similar, even though they have no string similarity, you will be limited in matching the variations that different data sources will provide. For more accurate results, it is important to semantically tokenize the strings so that your algorithms can work on a normalized, conceptual view of the products.

Some algorithmic technique might be helpful in dealing with these word synonyms, but if the domain vocabulary is restricted, it may even be feasible to manually curate the important variations and their parts of speech. Whether algorithmic or hand curated, you will need to encode this domain knowledge so that it is dependent on the product’s context. The string “apple” may be referring to a popular brand, a deciduous fruit or the scent of a hair care product. Category and peripheral information about the product will be needed to disambiguate “apple” and similar strings.

“Algorithms are for people who don’t know how to buy RAM.”

NLP Will Not Save You

Product titles are not amenable to generic natural language processing (NLP) solutions. Product titles are not well-formed sentences and have their own structure that often varies by the person or company that crafted them. Thinking that product matching can be solved with some off-the-shelf NLP techniques is a mistake. There are some NLP techniques that can be applied, but they have to be carefully tailored to work in this domain.

Consider the relative importance of word order between product titles for consumer electronics and for books. For electronics, the title word order does not really matter: “LCD TV 55 inch Sony” is not semantically different from “Sony 55 inch LCD TV”. Yet if you change the order of two words in a book’s title, you now have something completely different. “The Book of the Moon” and “The Moon Book” are two completely different books.

Product descriptions offer the best opportunity for the use of NLP techniques, since they tend to be natural language descriptions. Unfortunately, all sorts of peripheral concepts are included in the descriptions and this makes it hard to use them for product matching. It is also true that the descriptions for similar, but not identical products tend to look very similar. The best use of descriptions is in helping to determine the product’s category, which can help with matching, but do not expect that it will provide a strong signal for matching.

“If you find a solution and become attached to it, the solution may become your next problem.”

Design for Errors

Neither the input product data nor your matching algorithm will be 100% accurate. You need to make sure your algorithms are not rigidly expecting consistent data. This includes being able to compensate and/or correct bad data when it is detected. This is easier said than done, especially because we have all been conditioned to prefer more elegant and/or understandable code. Software code can look quite poetic when you do not have to litter it with constant sanity checks for edge cases and all the required exception handling this leads to. Unfortunately, the real world of crawl and feed data is not very elegant, nor will your algorithms produce flawless results.

This assumption about imperfect data should not be limited to the technical side of the product. I believe it is critically important that product designers work closely with the algorithmic designers to understand the characteristics of the data and the nature of the errors since this can be critical in designing a good user experience. Different algorithmic choices can result in different types of errors, and only by working together can the trade-offs be evaluated and good choices made which will influence how the users will perceive the product matching accuracy.

As a simple example of how designers and engineers can work together to make a better solution, suppose the engineers build a matching algorithm that outputs some measure of confidence. In isolation, the engineers will have to find the right threshold to balance accuracy and coverage, then declare matches for those above the threshold. In this scenario, the user interface designer only knows whether or not there are matches, so the interface is designed with the wording that says “matching products”. If these products are on the lower end of the confidence range, and they are bad matches, it will be a bad user experience.

Alternatively, if the designers are aware that there is a spectrum of match confidence, they could agree to expose those confidence values and instead of having to declare “matching products”, when the confidence is lower, they might opt to use softer wording like “similar products”, maybe even positioning them differently on the page. A user will not be quite as disappointed in the matching if they were only promised “similar” products.

“There are two ways to write error-free programs; only the third one works.” — Alan J. Perlis

Choose the Right Metrics

Suppose you have built your matching system, and an evaluation system to go along with it, then find out the accuracy rate is 95%. Assuming your system is giving reasonably good coverage, and in the presence of bad and missing data, this is definitely an impressive achievement. But what if within that 5% of the errors lies the current most popular products? If you weight error frequency by number of page views, the effective accuracy rate is going to be much, much lower. All the people viewing those mismatched product are not going to be impressed with your algorithm.

Even without considering weighting by page views, consider a situation where you display 20 products at a time on a page. With a 5% error rate, on average every page you show contains an error. Defined differently, this means your error rate is not 5% but 100%.

Matching algorithms will not be perfect, and even near perfect algorithms will need help. This help usually comes in the form of providing tools that allow human intervention to influence the overall quality or to influence the algorithmic output. When you are making an error on a highly visible product, someone should be able to be able to quickly override the algorithmic results to fix the problem.

“Williams and Holland’s Law: If enough data is collected, anything may be proven by statistical methods.”

Are We Done Yet?

There is no shortage of other product matching topics to discuss and interesting details to dive into. These first two blog posts have tried to capture some of the higher-level considerations. Future articles will provide more detailed examinations of these topics and some of the approaches we have taken in Bazaarvoice’s product matching systems.
Full Consistency Lag for Eventually Consistent Systems

A distributed data system consisting of several nodes is said to be fully consistent when all nodes have the same state of the data they own. So, if record A is in State S on one node, then we know that it is in the same state in all its replicas and data centers.

Screen Shot 2015-02-23 at 11.24.22 AM

Full Consistency sounds great. The catch is the CAP theorem that states that its impossible for a distributed system to simultaneously guarantee consistency (C), availability (A), and partition tolerance (P). At Bazaarvoice, we have sacrificed full consistency to get an AP system and contend with an eventually consistent data store. One way to define eventual consistency is that there is a point in time in the past before which the system is fully consistent (full consistency timestamp, or FCT). The duration between FCT and now is called the Full Consistency Lag (FCL).

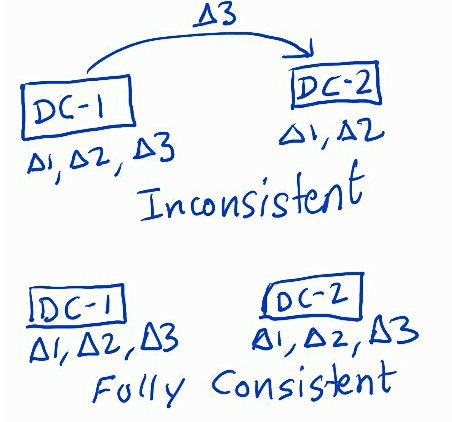
An eventually consistent system may never be in a fully consistent state given a massive write throughput. However, what we really want to know deterministically is the last time before which we can be assured that all updates were fully consistent on all nodes. So, in the figure above, in the inconsistent state, we would like to know that everything up to Δ2 has been replicated fully, and is fully consistent. Before we get down to the nitty-gritty of this metric, I would like to take a detour to set up the context of why it is so important for us to know the full consistency lag of our distributed system.

At Bazaarvoice, we employ an eventually consistent system of record that is designed to span multiple data centers, using multi-master conflict resolution. It relies on Apache Cassandra for persistence and cross-data-center replication.

One of the salient properties of our system of record is immutable updates. That essentially means that a row in our data store is simply a sequence of immutable updates, or deltas. A delta can be a creation of a new document, an addition, modification, or removal of a property on the document, or even a deletion of the entire document. For example, a document is stored in the following manner in Cassandra, where each delta is a column of the row.

Δ1 { “rating”: 4,
“text”: “I like it.”}
Δ2 { .., “status”: “APPROVED” }
Δ3 { .., “client”: “Walmart” }

So, when a document is requested, the reader process resolves all the above deltas (Δ1 + Δ2 + Δ3) in that order, and produces the following document:

{ “rating”: 4,
“text”: “I like it.”,
“status”: “APPROVED”,
“client”: “Walmart”,
“~version”: 3 }

Note that these deltas are stored as key-value pairs with the key as Time UUID. Cassandra would thus always present them in increasing order of insertion, making sure the last-write-wins property. Storing the rows in this manner allows us massive non-blocking global writes. Writes to the same row from different data centers across the globe would eventually achieve a consistent state without making any cross-data center calls. This point alone warrants a separate blog post, but it will have to suffice for now.

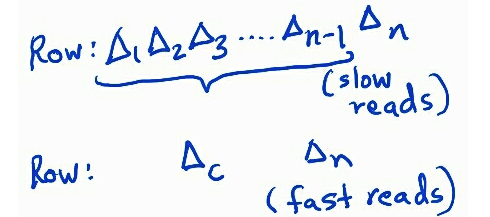
To recap, rows are nothing but a sequence of deltas. Writers simply append these deltas to the row, without caring about the existing state of the row. When a row is read, these deltas are resolved in ascending order and produce a json document.

There is one problem with this: over time rows will accrue a lot of updates causing the row to become really wide. The writes will still be OK, but the reads can become too slow as the system tries to consolidate all those deltas into one document. This is where compaction helps. As the name suggests, compaction resolves several deltas, and replaces them with one “compacted” delta. Any subsequent reads will only see a compaction record, and the read slowness issue is resolved.

Screen Shot 2015-03-14 at 9.18.29 PM

Great. However, there is a major challenge that comes with compaction in a multi-datacenter cluster. When is it ok to compact rows on a local node in a data center? Specifically, what if an older delta arrives after we are done compacting? If we arbitrarily decide to compact rows every five minutes, then we run the risk of losing deltas that may be in flight from a different data center.

To solve this issue, we need to figure out what deltas are fully consistent on all nodes and only compact those deltas, which basically is to say, “Find time (t) in the past, before which all deltas are available on all nodes”. This t, or full consistency timestamp, assures us that no deltas will ever arrive with a time UUID before this timestamp. Thus, everything before the full consistency timestamp can be compacted without any fear of data loss.

There is just one issue. This metric is absent in out of the box AP systems such as Cassandra. To me, this is a vital metric for an AP system. It would be rare to find a business use case in which permanent inconsistency is tolerable.

Although Cassandra doesn’t provide the full consistency lag, we can still compute it in the following way:

Tf = Time no hints were found on any node
rpc_timeout = Maximum timeout in cassandra that nodes will use when communicating with each other.

FCT = Full Consistency Timestamp
FCL = Full Consistency Lag

FCT = Tf – rpc_timeout
FCL = Tnow – FCT

The concept of Hinted Handoffs was introduced in Amazon’s dynamo paper as a way of handling failure. This is what Cassandra leverages for fault-tolerant replication. Basically, if a write is made to a replica node that is down, then Cassandra will write a “hint” to the coordinator node and try again in a configured amount of time.

We exploit this feature of Cassandra to get us our full consistency lag. The main idea is to poll all the nodes to see if they have any pending hints for other nodes. The time when they all report zero (Tf) is when we know that there are no failed writes, and the only pending writes are those that are in flight. So, subtracting the cassandra timeout (rpc_timeout) will give us our full consistency lag.
Now, that we have our full consistency lag, this metric can be used to alert the appropriate people when the cluster is lagging too far behind.

Finally, you would want to graph this metric for monitoring.

FCTMonitor

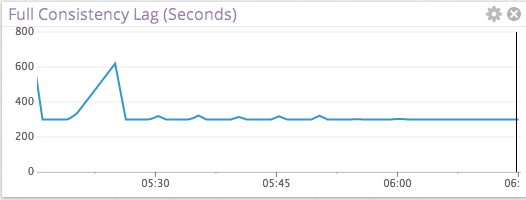
Note that in the above graph we artificially added a 5 minute lag to our rpc_timeout value to avoid excessively frequent compactions. We periodically poll for full consistency every 300 seconds (or 5 minutes). You should tweak this value according to your needs. For our settings above, the expected lag is 5 minutes, but you can see it spike at 10 minutes. All that really says is there was one time when we checked and found a few hints. The next time we checked (after 5 minutes in our case) all hints were taken care of. You can now set an alert in your system that should wake people up if this lag violates a given threshold–perhaps several hours–something that makes sense for your business.

Automated Product Matching, Part I: Challenges

Bazaarvoice’s flagship product is a platform for our clients to accept, display and manage consumer generated content (CGC) on their web sites. CGC includes reviews, ratings, images, videos, social network content, etc. Over the last few years, syndicating CGC from one site to another has become increasingly important to our customers. When a user submits a television review on Samsung’s branded web site, it benefits Samsung, Target and the consumer when that review can be shown on Target’s retail web site.

Before syndicating CGC became important to Bazaarvoice, our content could be isolated for each individual client. There was never any need for us to consider the question of whether our clients had any overlap in their product catalogs. With syndication, it is now vital for us to be able to match products across all our clients’ catalogs.

The product matching problem is not unique to Bazaarvoice. Shopping comparison engines, travel aggregators and ticket brokers are among the other domains that require comprehensive and scalable automated matching. This is a common enough problem that there are even a number of companies trying to grow a business based on providing product matching as a service.

Overview

I have helped design and build product matching systems five different times across two different domains and will share some of what I have learned about the characteristics of the problem and its solutions. This article will not be about specific algorithms or technologies, but guidelines and requirements that are needed when considering how to design a technical solution. This will address not just the algorithmic challenges, but also the equally important issues with designing product matching as a system.

Blog posts are best kept to a modest length, and I have many more thoughts to share on this topic than would be polite to include in a single article, so I have divided this discussion into two parts. This blog post is about the characteristics that make this an interesting and challenging problem. The second posting will focus on guidelines to follow when designing a product matching system.

The focus here will be on retail product matching, since that is where my direct experience lies. I am sure that there are additional lessons to be learned in other domains, but I think many of these insights may be more broadly applicable.

“If at first you don’t succeed, you must be a programmer.”

Imprecise Requirements

Product matching is one of those problems that initially seems straightforward, but whose complexity is revealed only after having immersed oneself in it. Even the most enlightened product manager is not going to have the time to spell out, in detail, how to deal with every nuance that arises. Understanding problems in depth, and filling in the large numbers of unspecified items with reasonably good solutions is why many software engineers are well paid. It is also what makes our jobs more interesting than most, since it allows us to invoke our problem solving and design skills, which we generally prefer to rote execution of tasks.

I am not proposing that the engineers should fill in all the details without consulting the product managers and designers, I only mean that the engineers should expect the initial requirements will need to be refined. Ideally both will work to fill in the gaps, but the engineers should expect they will be the ones uncovering and explaining the gaps.

“I have yet to see any problem, however complicated, which, when you looked at it in the right way, did not become still more complicated.” — Poul Anderson

What is a “Product”?

Language is inherently imprecise. The same word can refer to completely different concepts at different times and yet it causes no confusion when the people conversing share the same contextual information. On the other hand, software engineers creating a data model have to explicitly enumerate, encode, and give names to all the concepts in the system. This is a fundamental difference between how the engineers and others view the problem and can be a source of frustration when engineers begin to inject questions into the requirements process such as: “What is a product?”. Those that are not accustomed to diving into the concepts underlying their use of a word can often feel like this is a time-wasting, philosophical discussion.

I’ve run across 8 distinct concepts where the word “product” has been used. The most basic difference lies between those “things” that you are trying to match and the “thing” you are using as the basis of the match. Suppose you get a data feed from Acme, Inc. which includes a thing called an “Acme Giant Rubber Band” and that you also crawled the Kwik-E-Mart web site, which yielded a thing called an “Acme Giant Green Rubber Band”. You then ask the question, are these the same “product”? Here we have an abstract notion of a specific rubber band in our mind and we are asking the question of whether these specific items from those two data sources match this concept.

Now let us also suppose that the “Acme Giant Rubber Band” item in the Acme data feed has listed 6 different UPC values, which correspond to 6 different colors they manufacturer for the product. This means that the “thing” in the feed is really a set of individual items, while the “Acme Giant Green Rubber Band” we saw on the Kwik-E-Mart web site just is a single item. These two items are similar, but not identical product-related concepts.

With just this simple example, there are 3 different concepts floating around, yet for each of them the “product” is often the word people will use. For most domains, when you really start to explore the data model that is required, more than three product-related concepts will likely be needed.

Software designers must carefully consider how many different “product” concepts they need to model and those helping to define the requirements should appreciate the importance of, and invest time in understanding the differences between the concepts. The importance of getting this data model correct from the start cannot be stressed enough.

“If names are not correct, then language is not in accord with the truth of things. If language is not in accord with the truth of things, then affairs cannot be carried out successfully.” — Confucius

Equality for All?

You should start with the most basic of questions: What is a “match”? My experience working on product matching in different domains and varying use cases is that there is not a single definition of product equality that applies everywhere. For those that have never given product matching much thought beyond their intuition, this might seem like an odd statement: two products are either the same or they are not, right? By way of example, here is an illustration of why different use cases require different notions of equality.

Suppose you are shopping for some 9-volt batteries and you are interested in seeing which brands tend to last longer based on direct user experience. You do a search, you navigate through some web site and then will likely need to make a choice at some point: are you looking to buy the 2-pack, the 4-pack or the 8-pack?

Having to make a quantity choice at this point may be premature, but you usually have to make this choice to get at the review content. However, the information you are looking for, and likely the bulk of the review content, is independent of the size of the box in which it is packaged. Requiring a quantity choice to get at review content may just be a bad user experience, but regardless of that, you certainly would not want to miss out on relevant review content simply because you had chosen the wrong quantity at this point in your research.

The conclusion here is that reviews posted to the web page for the 2-pack and reviews posted for the page of an 8-pack should probably not be fragmented. Therefore, for the purposes of review content, these two products, which would have different UPC and/or EAN values, should be considered equivalent.

Now suppose you have made your decision on the brand of battery to buy and now you are looking for the best price on an 8-pack. For a price comparison, you most definitely do not want to be comparing the 2-pack prices along with its 8-pack equivalent. Here, for price comparisons, these two products should definitely not be considered equivalent.

Understanding that product equivalence varies by context is not only important for designing algorithms and software systems, but has a lot of implications for creating better user experiences. For the companies looking to offer product matching as a service, the flexibility they offer in tailoring the definition of equality for their clients will be an important factor in how broadly applicable their solutions will be.

“It is more important to know where you are going than to get there quickly. Do not mistake activity for achievement.” — Isocrates

Imperfect Data Sources

If all the products you need to match have been assigned a globally unique identifier, such as a UPC, EAN or ISBN, and you have access to that data, and the data can be trusted, then product matching could be trivial. However, not all products get assigned such a number and for those that do, you do not always have access to those values. As discussed, it is also true that a “match” cannot always be defined simply by the equality of unique identifiers.

Those that crawl the web for product data tend to think that a structured data feed is the answer to getting better data. However, the companies that create product feeds vary greatly in their competency. Even when competent, they may build their feed from one system’s database, while more useful information may be stored in another system. Further, the competitive business landscape can result in companies wanting to deliberately suppress or obfuscate identifying information. You also have the ubiquitous issues of software bugs and data entry errors to contend with. All these realities add up to the fact that data feeds are not a panacea for product matching.

So while we have the web crawling folks wishing for feed data, we simultaneously have the feed processing folks wishing for crawled data to fill in their gaps. The first piece of advice for building a product matching system is to assume you will need to accept data from a variety of data sources. The ability to fill in data gaps with alternative sources will allow you to get the best of both worlds. This also means you may not only be trying to match products between different sites, but you may need to match products within the same site and merge the data from different sources to form a single view of a product at a site. I know of one very large shopping comparison site that did not design for this case and found themselves without the ability to support particular types of new business opportunities.

“If you think the problem is bad now, just wait until we’ve solved it.” — Arthur Kasspe

Look Before You Leap

The specific algorithms and technologies one chooses for an automated product matching system should not be the primary focus. It is very tempting for us information scientists and engineers to dive right into the algorithmic and technical solutions. After all, this is predominantly what universities have trained us to focus on and, in some sense, is the more interesting part of the problem. You can choose almost any one of a host of algorithms and get some form of product matching fairly quickly. Depending on your specific quality requirements, a simple system may be enough, but if there are higher expectations for a matching system, you will need a lot more than just a fancy algorithm.

When more than simple matching is needed, it will not be the algorithm you use, but how you use the algorithm that will matter. This means really understanding the characteristics of the problem in the context of your domain. It is also important not to define the problem too narrowly. There are a bunch of seemingly tangential issues in product matching that are very easy to put into the bucket of “we can deal with that later”, but which turn out to be very hard to deal with after the fact. It is how well you handle all of these practical details that will most influence the overall success of the project.

Choosing a simplistic data model is an example where it may seem like a good starting approach. However, this will wind up being so deeply ingrained in the software, that it will become nearly impossible to change. You wind up with either serious capability limitations or a series of kludges that both complicate your software and lead to unintended side effects. I learned this from experience.

“A doctor can bury his mistakes but an architect can only advise his clients to plant vines.” — Frank Lloyd Wright

Up Next

This posting covers some of the important characteristics of the product matching problem. In the sequel, there will be some more specific guidelines for building matching systems.

Scoutfile: A module for generating a client-side JS app loader

A couple of years ago, my former colleague Alex Sexton wrote about the techniques that we use at Bazaarvoice to deploy client-side JavaScript applications and then load those applications in a browser. Alex went into great detail, and it’s a good, if long, read. The core idea, though, is pretty simple: an application is bootstrapped by a “scout” file that lives at a URL that never changes, and that has a very short TTL. Its job is to load other static resources with long TTLs that live at versioned URLs — that is, URLs that change with each new deployment of the application. This strategy balances two concerns: the bulk of application resources become highly cacheable, while still being easy to update.

In order for a scout file to perform its duty, it needs to load JavaScript, load CSS, and host the config that says which JS and CSS to load. Depending on the application, other functionality might be useful: the ability to detect old IE; the ability to detect DOM ready; the ability to queue calls to the application’s methods, so they can be invoked for real when the core application resources arrive.

At Bazaarvoice, we’ve been building a lot of new client-side applications lately — internal and external — and we’ve realized two things: one, it’s very silly for each application to reinvent this particular wheel; two, there’s nothing especially top secret about this wheel that would prevent us from sharing it with others.

To that end, I’m happy to release scoutfile as an NPM module that you can use in your projects to generate a scout file. It’s a project that Lon Ingram and I worked on, and it provides both a Grunt task and a Node interface for creating a scout file for your application. With scoutfile, your JavaScript application can specify the common functionality required in your scout file — for example, the ability to load JS, load CSS, and detect old IE. Then, you provide any code that is unique to your application that should be included in your scout file. The scoutfile module uses Webpack under the hood, which means you can use loaders like json! and css! for common tasks.

The most basic usage is to npm install scoutfile, then create a scout file in your application. In your scout file, you specify the functionality you need from scoutfile:

var App = require('scoutfile/lib/browser/application');
var loader = require('scoutfile/lib/browser/loader');

var config = require('json!./config.json');
var MyApp = App('MyApp');

MyApp.config = config;

loader.loadScript(config.appJS);
loader.loadStyleSheet(config.appCSS);

Next, you can generate your scout file using a simple Node script:

var scout = require('scoutfile');
scout.generate({
  appModules: [
    {
      name: 'MyApp',
      path: './app/scout.js'
    }
  ],

  // Specify `pretty` to get un-uglified output.
  pretty: true
}).then(function (scout) {
  console.log(scout);
});

The README contains a lot more details, including how to use flags to differentiate production vs. development builds; how to configure the Grunt task; how to configure the “namespace” that is occupied on window (a necessary evil if you want to queue calls before your main application renders); and more.

There are also several open issues to improve or add functionality. You can check out the developer README if you’re interested in contributing.

Analyzing our global shopper network (part one)

Every holiday season, the virtual doors of your favorite retailer are blown open by a torrent of shoppers who are eager to find the best deal, whether they’re looking for a Turbo Man action figure or a ludicrously discounted 4K flat screen. This series focuses on our Big Data analytics platform, which is used to learn more about how people interact with our network.

The challenge

Within the Reporting & Analytics group, we use Big Data analytics to help some of the world’s largest brands and retailers understand how to most effectively serve their customers, as well as provide those customers with the information they need to make informed buying decisions. The amount of clickstream traffic we see during the holidays – over 45,000 events per second, produced by 500 million monthly unique visitors from around the world – is tremendous.

In fact, if we reserved a seat at the Louisiana Superdome for each collected analytics event, we would fill it up in about 1.67 seconds. And, if we wanted to give each of our monthly visitors their own seat in a classic Beetle, we’d need about 4.64 times the total number produced between 1938 and 2003. That’s somewhere in the neighborhood of a hundred million cars!

Fortunately for us, we live in the era of Big Data and high scalability. Our platform, which is based on the principles outlined in Nathan Marz’s Lambda architecture design, addresses the requirements of ad-hoc, near real-time, and batch applications. Before we could analyze any data, however, we needed a way to reliably collect it. That’s where our in-house event collection service, which we named “Cookie Monster,” came into the picture.

Collecting the data

When investigating how clients would send events to us, our engineers knew that the payload had to fit within the query string of an HTTP GET request. They settled upon a lightweight serialization format called Rison, which expresses JSON data structures, but is designed to support URI encoding semantics. (Our Rison plugin for Jackson, which we leverage to handle the processing of Rison-encoded events, is available on GitHub.)

In addition, we decided to implement support for client-side batching logic, which would allow a web browser to send multiple events within the payload of a single request. By sending fewer requests, we reduced the amount of HTTP transaction overhead, which minimized the amount of infrastructure required to support a massive network audience. Meanwhile, as their browsers would only need to send one request, end-users also saw a performance uptick.

Because the service itself needed a strong foundation, we chose the ubiquitous Dropwizard framework, which accelerated development by providing the basic ingredients needed to create a maintainable, scalable, and performant web service. Dropwizard glues together Jetty (a high-performance web server), Jersey (a framework for REST-ful web services), and Jackson (a JSON processor).

BDAP - Cookie Monster Event Collection - Diagram

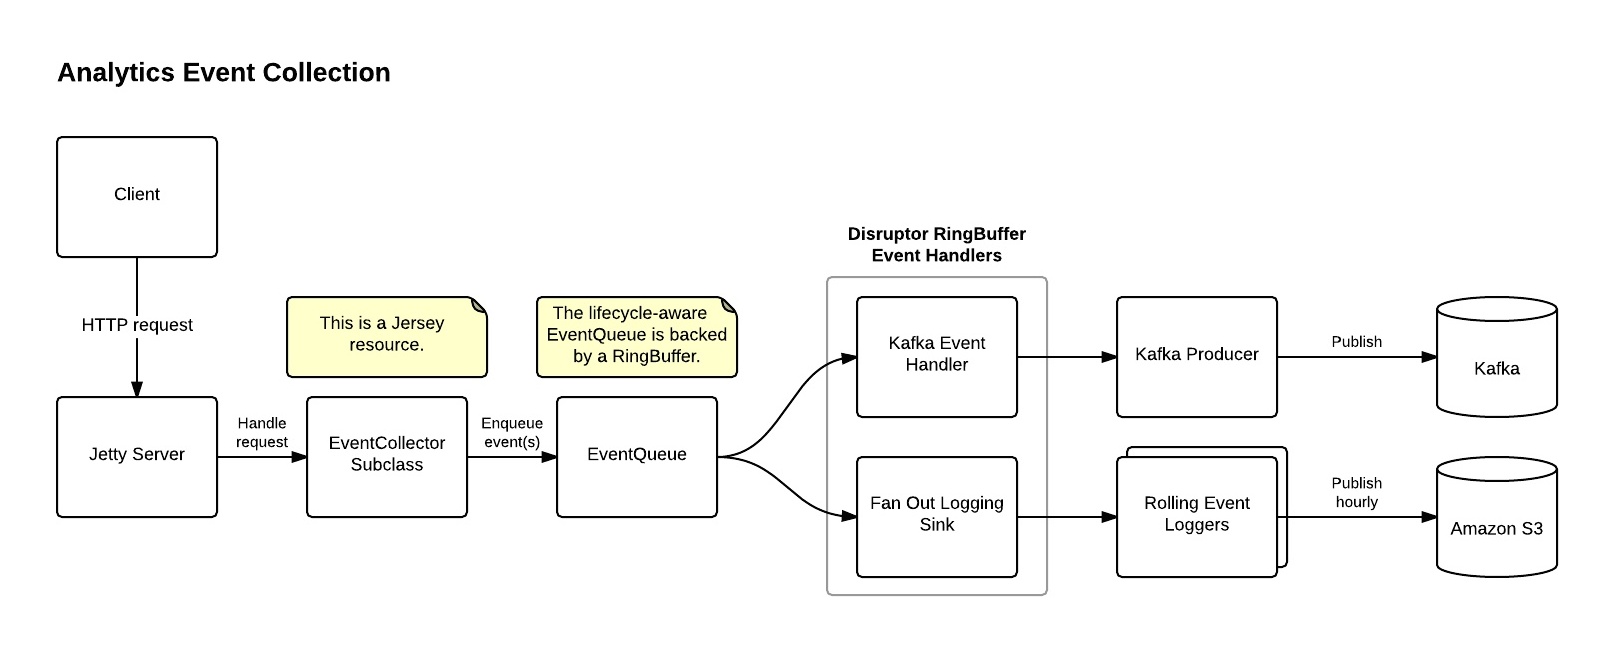
Perhaps most importantly, we used the Disruptor library‘s ring buffer implementation to facilitate very fast inter-thread messaging. When a new event arrives, it is submitted to the EventQueue by the EventCollector. Two event handler classes, which listen for ring events, ensure that the event is delivered properly. The first event handler acts as a producer for Kafka, publishing the event to the appropriate topic. (Part two of this series will discuss Kafka in further detail.)

The second is a “fan out” logging sink, which mods specific event metadata and delivers the corresponding event to the appropriate logger. At the top of every hour, the previous hour’s batch logs are delivered to S3, and then consumed by downstream processes.

In the real world

When building Cookie Monster, we knew that our service would need to maintain as little state as possible, and accommodate the volatility of cloud infrastructure.

Because EC2 is built on low-cost, commodity hardware, we knew that we couldn’t “cheat” with sophisticated hardware RAID – everything would run on machines that were naturally prone to failure. In our case, we deemed those trade-offs acceptable, as our design goals for a distributed system aligned perfectly with the intent of EC2 auto-scaling groups.

Even though the service was designed for EC2, there were a few hiccups along the way, and we’ve learned many valuable lessons. For example, the Elastic Load Balancer, which distributes HTTP requests to instances within the Auto Scaling group, must be “pre-warmed” before accepting a large volume of traffic. Although that’s by design, it means that good communication with AWS prior to deployment must be a crucial part of our process.

Also, Cookie Monster was designed prior to the availability of EBS optimized instances and provisioned IOPS, which allow for more consistent performance of an I/O-bound process when using EBS volumes. Even in today’s world, where both of those features could be enabled, ephemeral (i.e. host-local) volumes remain a fiscally compelling – if brittle – alternative for transient storage. (AWS generally discourages the use of ephemeral storage where data loss is a concern, as they are prone to failure.)

Ultimately, our choice to deploy into EC2 paid off, and it allowed us to scale the service to stratospheric heights without a dedicated operations team. Today, Cookie Monster remains an integral service within our Big Data analytics platform, successfully collecting and delivering many billions of events from all around the world.

Open sourcing cloudformation-ruby-dsl

Cloudformation is a powerful tool for building large, coordinated clusters of AWS resources. It has a sophisticated API, capable of supporting many different enterprise use-cases and scaling to thousands of stacks and resources. However, there is a downside: the JSON interface for specifying a stack can be cumbersome to manipulate, especially as your organization grows and code reuse becomes more necessary.

To address this and other concerns, Bazaarvoice engineers have built cloudformation-ruby-dsl, which turns your static Cloudformation JSON into dynamic, refactorable Ruby code.

https://github.com/bazaarvoice/cloudformation-ruby-dsl

The DSL closely mimics the structure of the underlying API, but with enough syntactic sugar to make building Cloudformation stacks less painful.

We use cloudformation-ruby-dsl in many projects across Bazaarvoice. Now that it’s proven its value, and gained some degree of maturity, we are releasing it to the larger world as open source, under the Apache 2.0 license. It is still an earlier stage project, and may undergo some further refactoring prior to it’s v1.0 release, but we don’t anticipate major API changes. Please download it, try it out, and let us know what you think (in comments below, or as issues or pull request on Github).

A big thanks to Shawn Smith, Dave Barcelo, Morgan Fletcher, Csongor Gyuricza, Igor Polishchuk, Nathaniel Eliot, Jona Fenocchi, and Tony Cui, for all their contributions to the code base.